Natural clinical instructions, written by participants
Rather than perturbing a fixed template, this study tested naturally written clinical task instructions. In Open (Clinical) LLMs are Sensitive to Instruction Phrasings, Alberto Mario Ceballos Arroyo, Monica Munnangi, Jiuding Sun, Karen Y.C. Zhang, Denis Jered McInerney, Byron C. Wallace, and Silvio Amir asked medical professionals to write task instructions; the paper reports a final instruction collection from 12 participants.
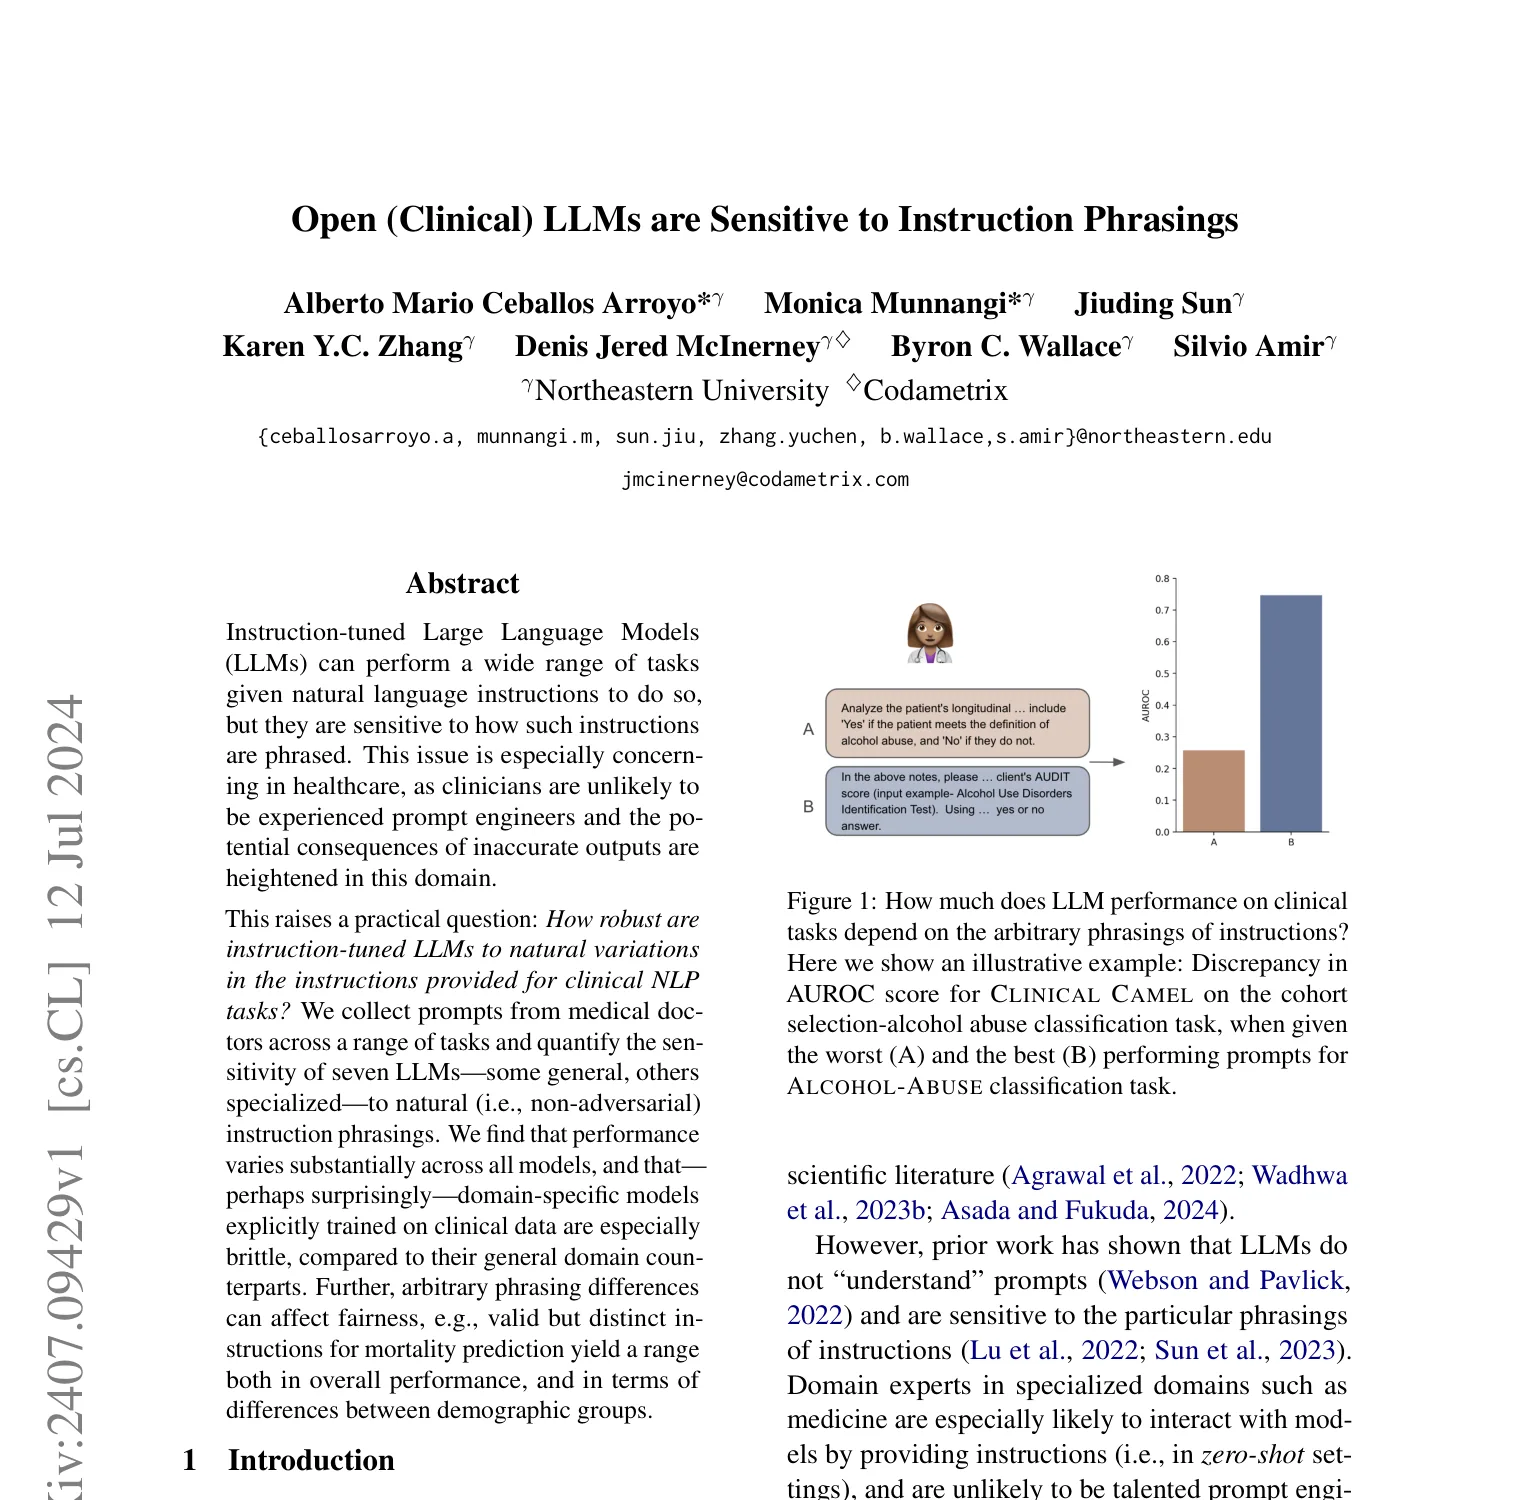
The evaluation covered ten clinical classification tasks and six information-extraction tasks drawn from MIMIC-III and prior i2b2/n2c2 challenges. Four models were general-domain and three were trained for clinical use. For the same task and examples, the researchers measured performance across alternate instructions. The gap between best and worst instructions reached an absolute difference of 0.6 in AUROC for classification tasks and 0.4 in F1 for extraction tasks. The authors also found variation in demographic fairness measures; clinical-domain models were not uniformly less brittle than general models.
A good prompt was not a stable prompt
The comparison shows why choosing the single best phrasing can give a misleading view of expected performance. It also does not establish that clinical models are generally worse: results differed by task and model, and the experiments covered a particular set of instruction writers and datasets.
The authors flag important limits. The open-source model sample may not represent commercial systems, participating clinicians were not necessarily representative of future users, and classification scores were inferred from first-token logits rather than the final responses a user would read. For a clinical deployment, the unresolved check is whether performance and subgroup differences remain acceptable across the ordinary wording clinicians actually use.
Bibliography
- Alberto Mario Ceballos Arroyo, Monica Munnangi, Jiuding Sun, Karen Y.C. Zhang, Denis Jered McInerney, Byron C. Wallace, and Silvio Amir (2024). Open (Clinical) LLMs are Sensitive to Instruction Phrasings. arXiv:2407.09429v1. Full paper (PDF).