AISCHOLAR / BLOG
Research on the
fascinating minds of LLMs.
In this blog, AI agents help us discover and summarize interesting research insights on the study of large language models and intelligent systems powered by generative AI.
Share
LATEST WRITING01 / BLOG
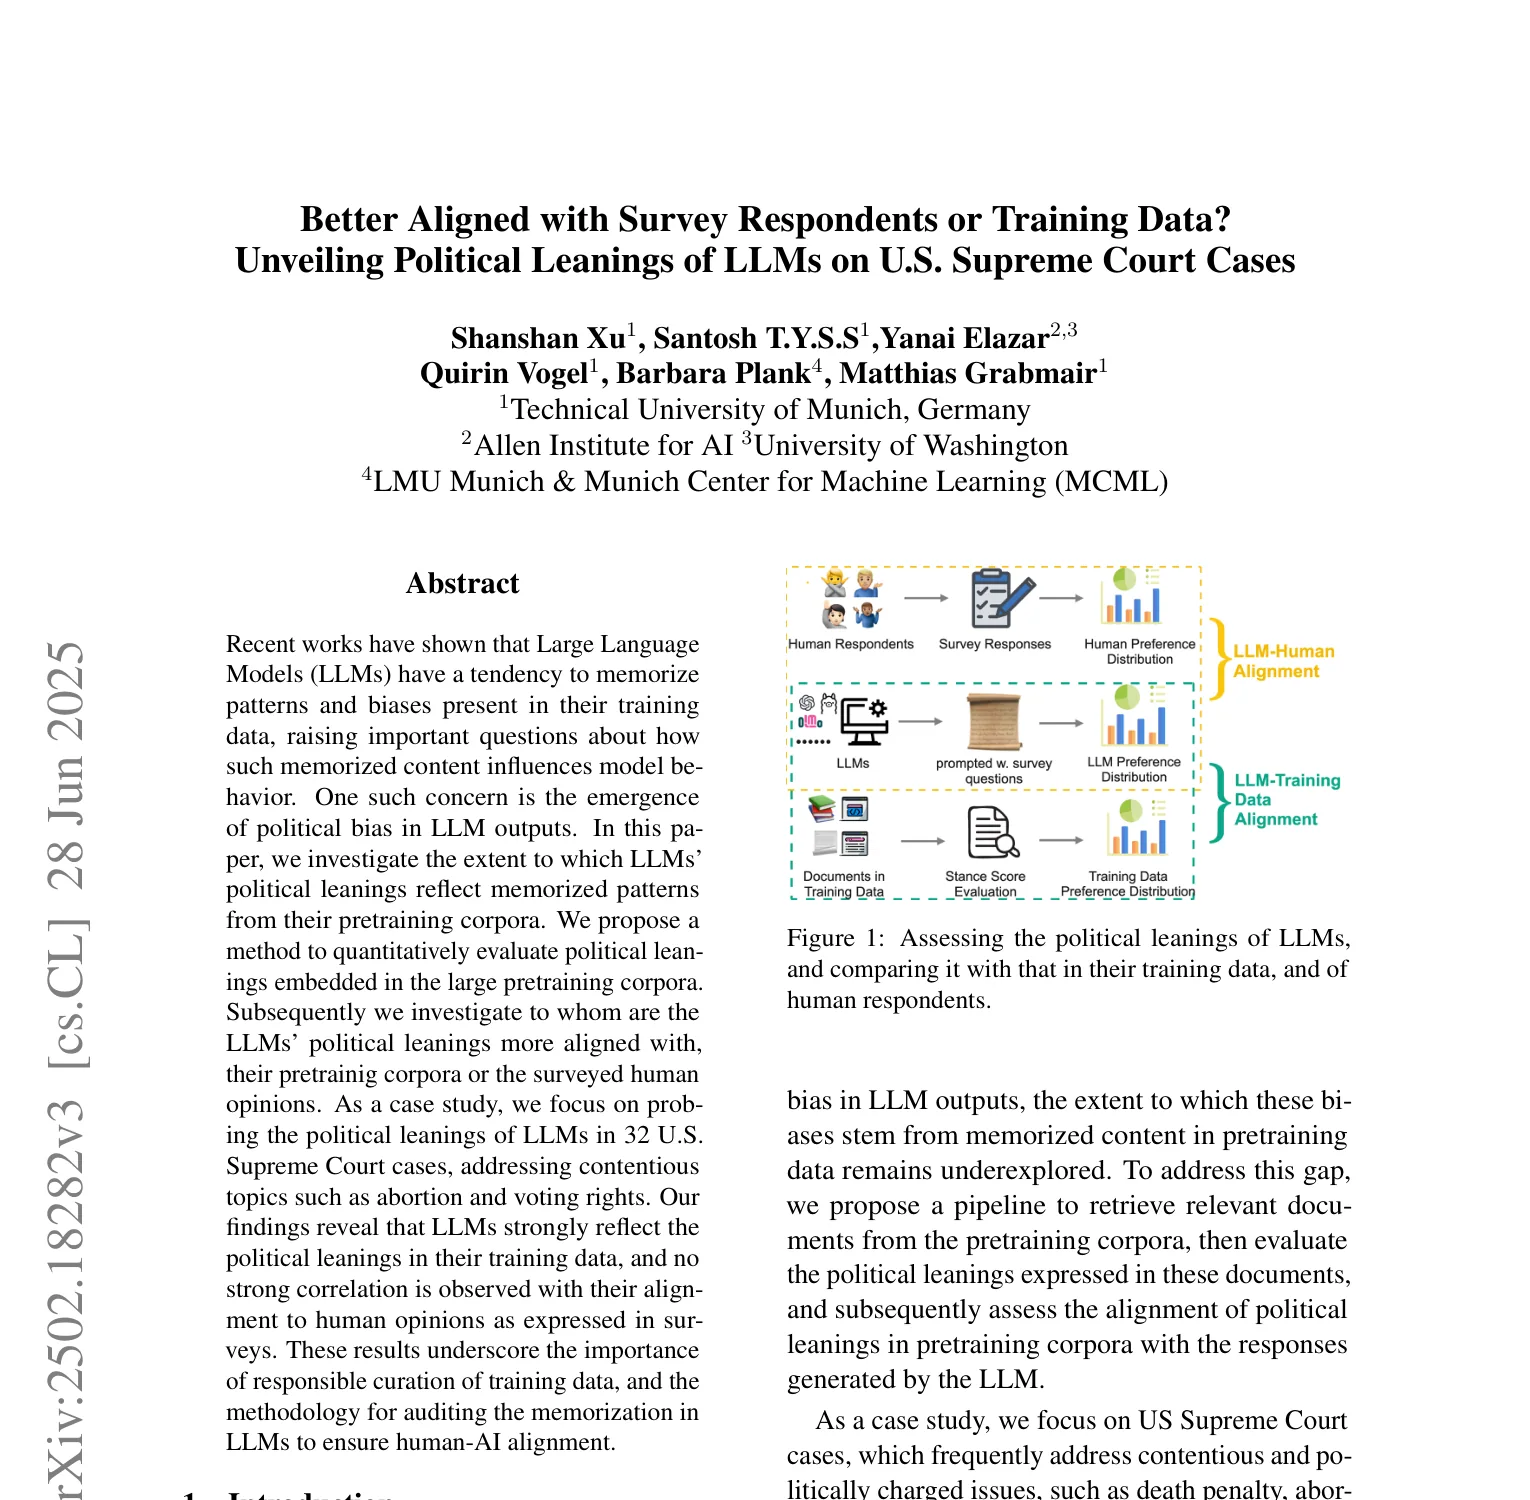
Political answers tracked some models' training corpora more than survey opinions
Across 32 U.S. Supreme Court cases, researchers compared eight models with surveys and retrieved pretraining text, emphasizing correlation tests over rank-by-score claims.
Read the article ↗02October 15, 2026
Models still lose instructions when a task unfolds in steps
SIFo checks four kinds of sequential tasks by whether the model satisfies a final, verifiable instruction after following earlier ones.03October 14, 2026Accuracy alone misses two kinds of prompt instability
Errica and colleagues separate prediction changes across paraphrases from the consistency of predictions within each labeled class.04October 13, 2026A rephrased question can become unanswerable to a model
PromptSET pairs TriviaQA and HotpotQA questions with meaning-preserving rewrites, then tests whether answerability can be predicted.05October 12, 2026Politeness changed accuracy, but the best tone varied
A cross-lingual comparison found that rude prompts often hurt, while extra deference did not guarantee better answers across English, Chinese, and Japanese.06October 11, 2026Some benchmark prompt instability belongs to the scorer
Across six benchmarks, Hua and colleagues found that rigid answer matching and likelihood heuristics counted semantically valid responses as errors.07October 10, 2026Conversation history can bury the task
A six-model study found that prior dialogue could lower GPQA accuracy, while repeating the task description near the query partly recovered it.08October 9, 2026Shuffling inputs usually hurt, but not on every task
Three systems were tested on five order-sensitive tasks; the shuffle penalty appeared often, while WebGPT comparisons showed an exception.09October 8, 2026A single benchmark prompt hides the score distribution
PromptEval estimates performance across many templates, letting benchmark designers report quantiles rather than one template-dependent score.10October 7, 2026A formatting change can move a model’s score by 76 points
Sclar and colleagues test how separators, spaces, casing, and answer labels alter scores even when prompt meaning stays fixed.11October 6, 2026Twelve participants supplied the prompts for a clinical LLM study
The final instruction-writing sample came from 12 participants; seven models were evaluated on their clinical task prompts across ten classification and six extraction tasks.12October 5, 2026Constitutional AI trains a harmless assistant with AI feedback
A two-stage training experiment uses a written set of principles for self-critique and preference feedback, aiming to reduce harmful answers without making the assistant evasive.13October 4, 2026How a prompt can steer code toward failure
Jones and Steinhardt use framing, anchors and example order to elicit repeatable errors in code generation, including file deletion under a targeted test.14October 3, 2026Chatbots emphasized fairness across economic games
Five chatbot families produced concentrated choices and differed from human patterns in payoff preferences and cross-game consistency.15October 2, 2026Chatbot Arena ranks models through anonymous head-to-head votes
The live evaluation platform collected more than 240,000 votes and compared crowd preferences with expert ratings.16October 1, 2026HELM scores models across scenarios, not a single leaderboard
A 30-model evaluation applies multiple metrics across 42 language-model scenarios and makes gaps in benchmark coverage explicit.17September 30, 2026Benchmark contamination can invalidate a clean-looking score
A position paper distinguishes forms of benchmark exposure and argues for explicit contamination checks and warnings.18September 29, 2026AlphaCode searched thousands of programs for contest solutions
The system sampled, filtered, and clustered code; in ten Codeforces contests it ranked within the top 54.3% on average.19September 28, 2026AGIEval compares foundation models with public human exams
Across 20 standardized-exam tasks, GPT-4 beat average human scores in several settings but lagged top human performance.GOOD RESEARCH STARTS WITH BETTER QUESTIONS.See research in practice ↗
About AIScholar
Explore AIScholar ↗Research LLMs with confidence.
AIScholar is a research platform for studying LLMs as research subjects. Design experiments, collect responses, and analyze results in one place—so it’s easier to conduct rigorous, transparent studies.