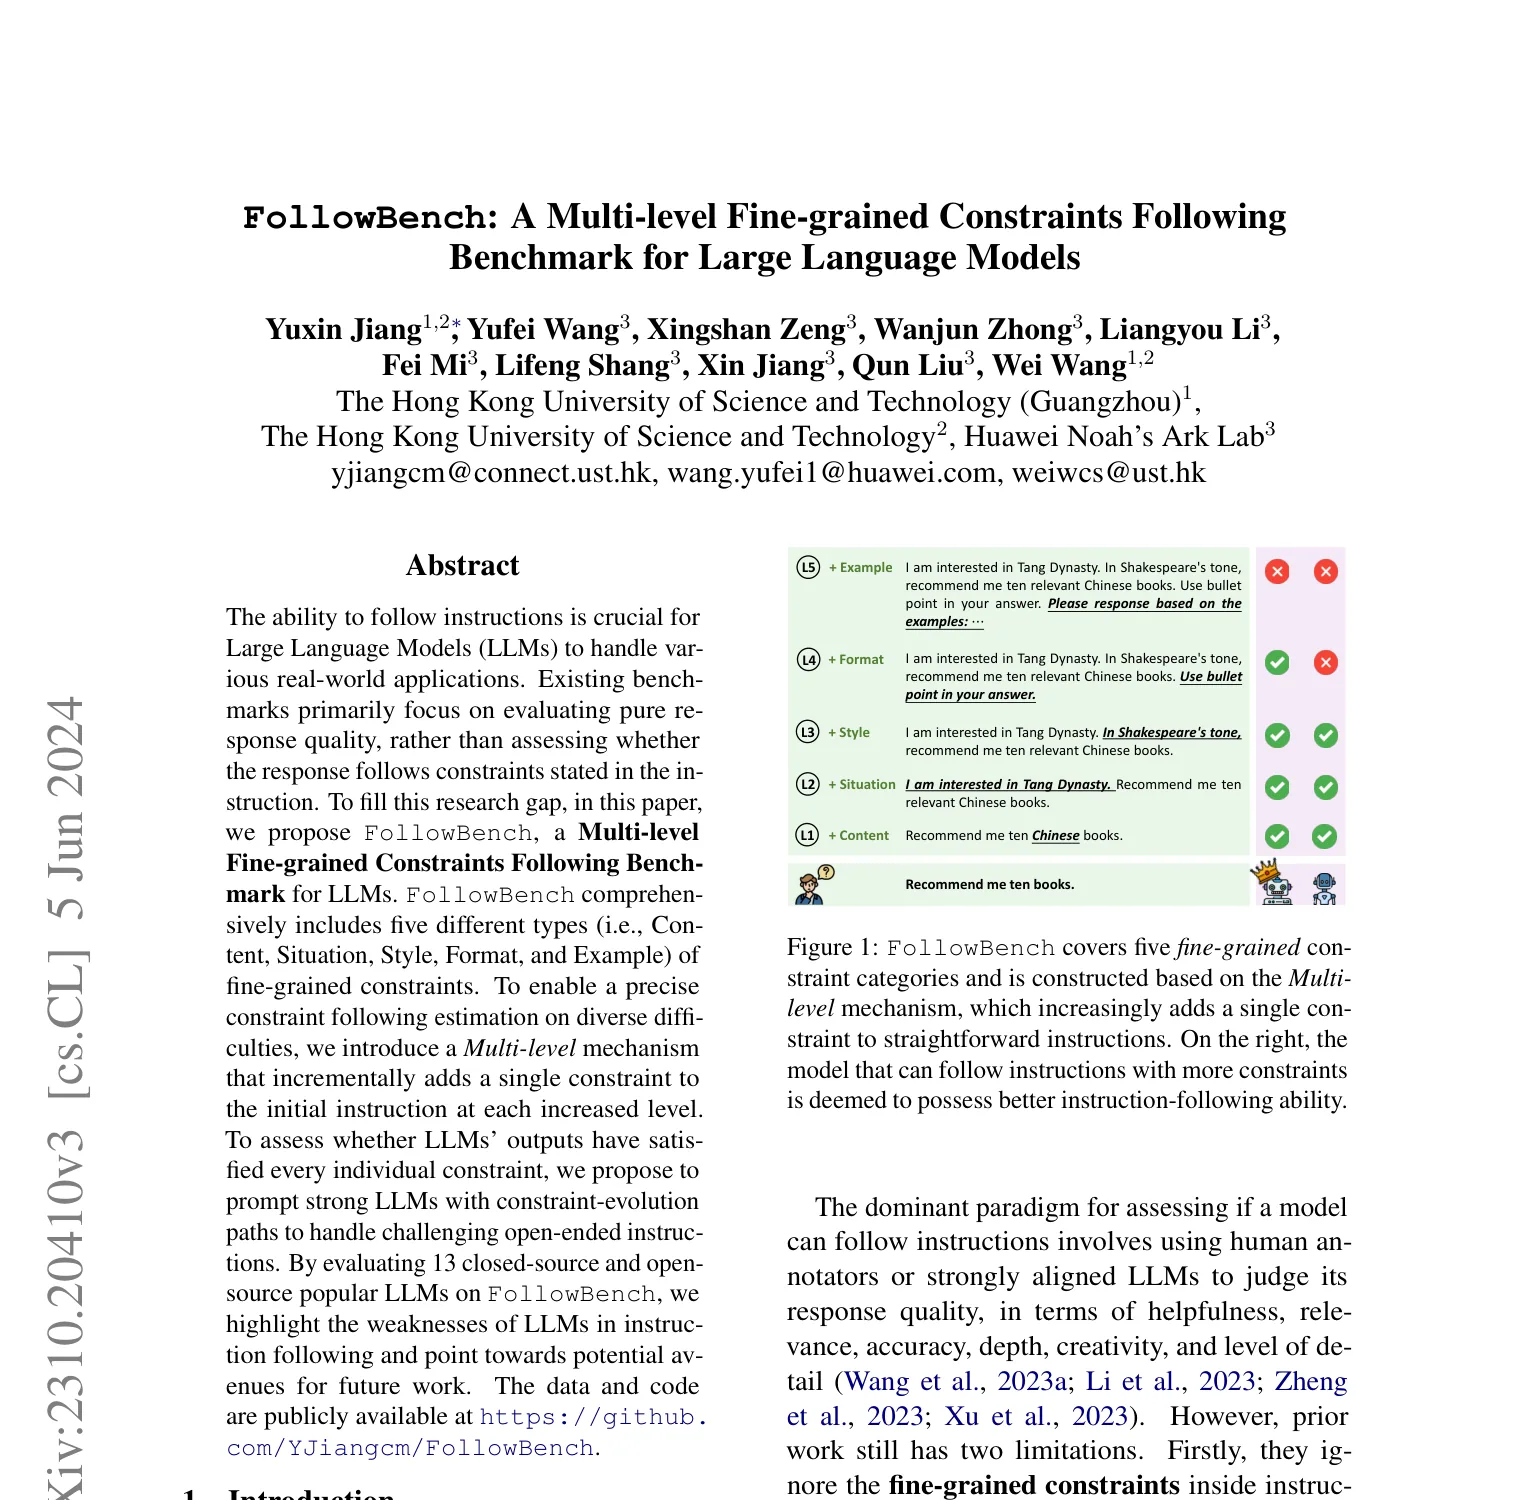
Each level adds another demand
A request can combine a topic, a situation, a style, a format, and examples to imitate. In FollowBench: A Multi-level Fine-grained Constraints Following Benchmark for Large Language Models, Jiang and colleagues make that buildup measurable by adding one constraint at each level. The benchmark includes five constraint types—content, situation, style, format, and example—and the authors evaluate 13 open- and closed-source models. Strong LLMs assess whether individual constraints were met.
Human agreement and a single-turn boundary
After revising the evaluator prompt, the authors report 88% agreement with expert human judgments. They also find that decoding temperature affects instruction-following scores for the tested models. The evaluator remains prompt-dependent, and the experiments cover single-round interactions; their score does not tell us how models respond when users clarify or revise a request over multiple turns. That follow-up is the specific extension left open by FollowBench's controlled progression.
Bibliography
- Jiang, Y., Wang, Y., Zeng, X., Zhong, W., Li, L., Mi, F., Shang, L., Jiang, X., Liu, Q., & Wang, W. (2023). FollowBench: A Multi-level Fine-grained Constraints Following Benchmark for Large Language Models. arXiv:2310.20410v3 [cs.CL]. https://arxiv.org/pdf/2310.20410