HumanEval gains many more test inputs
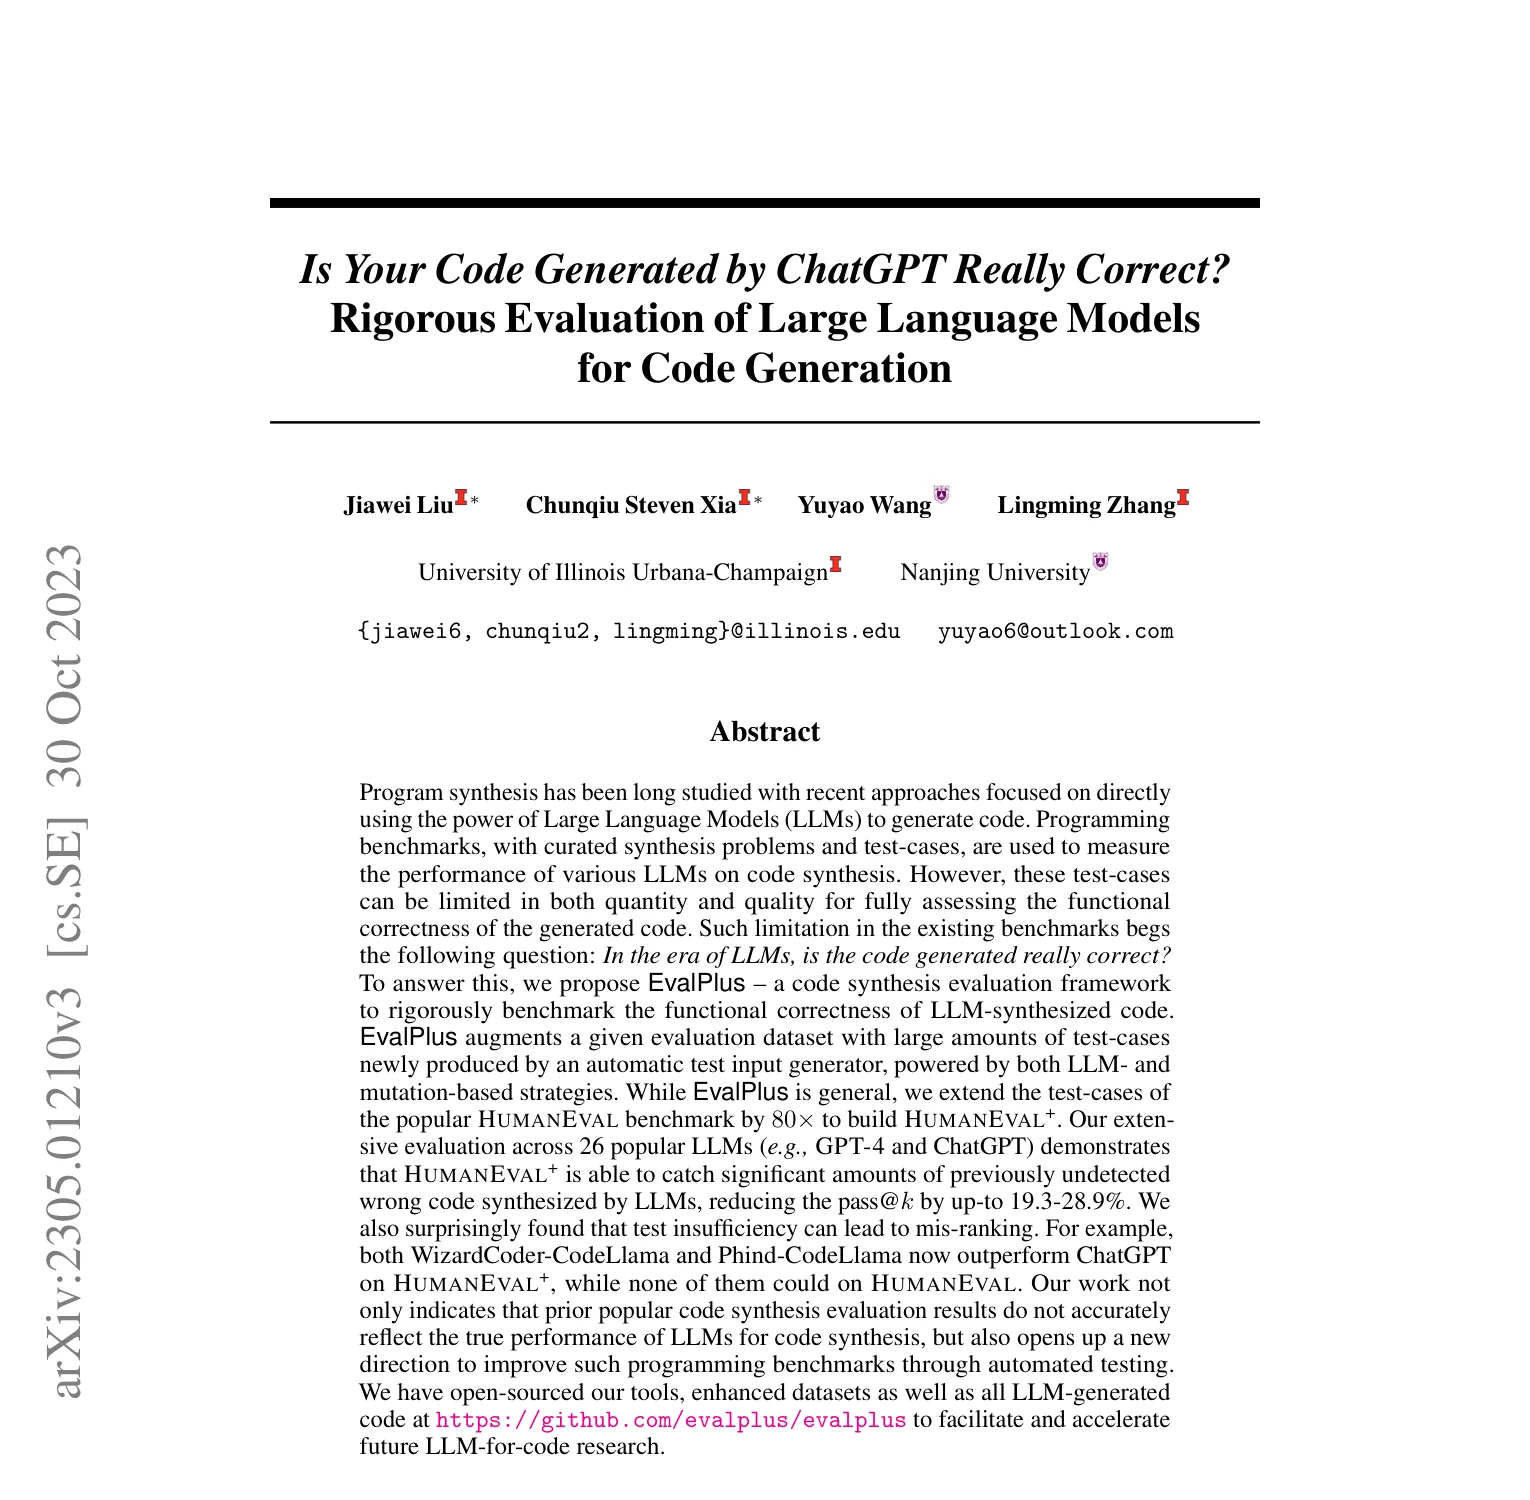
A generated function can pass a benchmark's examples and still fail on an untested input. Liu and colleagues address test-suite coverage in Is Your Code Generated by ChatGPT Really Correct? Rigorous Evaluation of Large Language Models for Code Generation. Their EvalPlus framework expands tests using LLM- and mutation-based input generation; HumanEval+ contains 80 times the test cases of HumanEval.
Across 26 language models, the authors report that HumanEval+ reduces pass@k by up to 19.3–28.9%. Additional cases also alter rankings: WizardCoder-CodeLlama and Phind-CodeLlama outperform ChatGPT on HumanEval+ in comparisons where neither did on the original benchmark.
The pass rate remains test-dependent
These tests catch previously missed incorrect programs, but sampled inputs cannot prove correctness on every possible case. The magnitude of a score change depends on the tasks, generated tests, and model outputs under evaluation. The ranking reversal is itself the paper's concrete warning: for these HumanEval results, model order changes when the test suite changes.
Bibliography
- Liu, J., Xia, C. S., Wang, Y., & Zhang, L. (2023). Is Your Code Generated by ChatGPT Really Correct? Rigorous Evaluation of Large Language Models for Code Generation. arXiv:2305.01210v3 [cs.SE]. https://arxiv.org/pdf/2305.01210