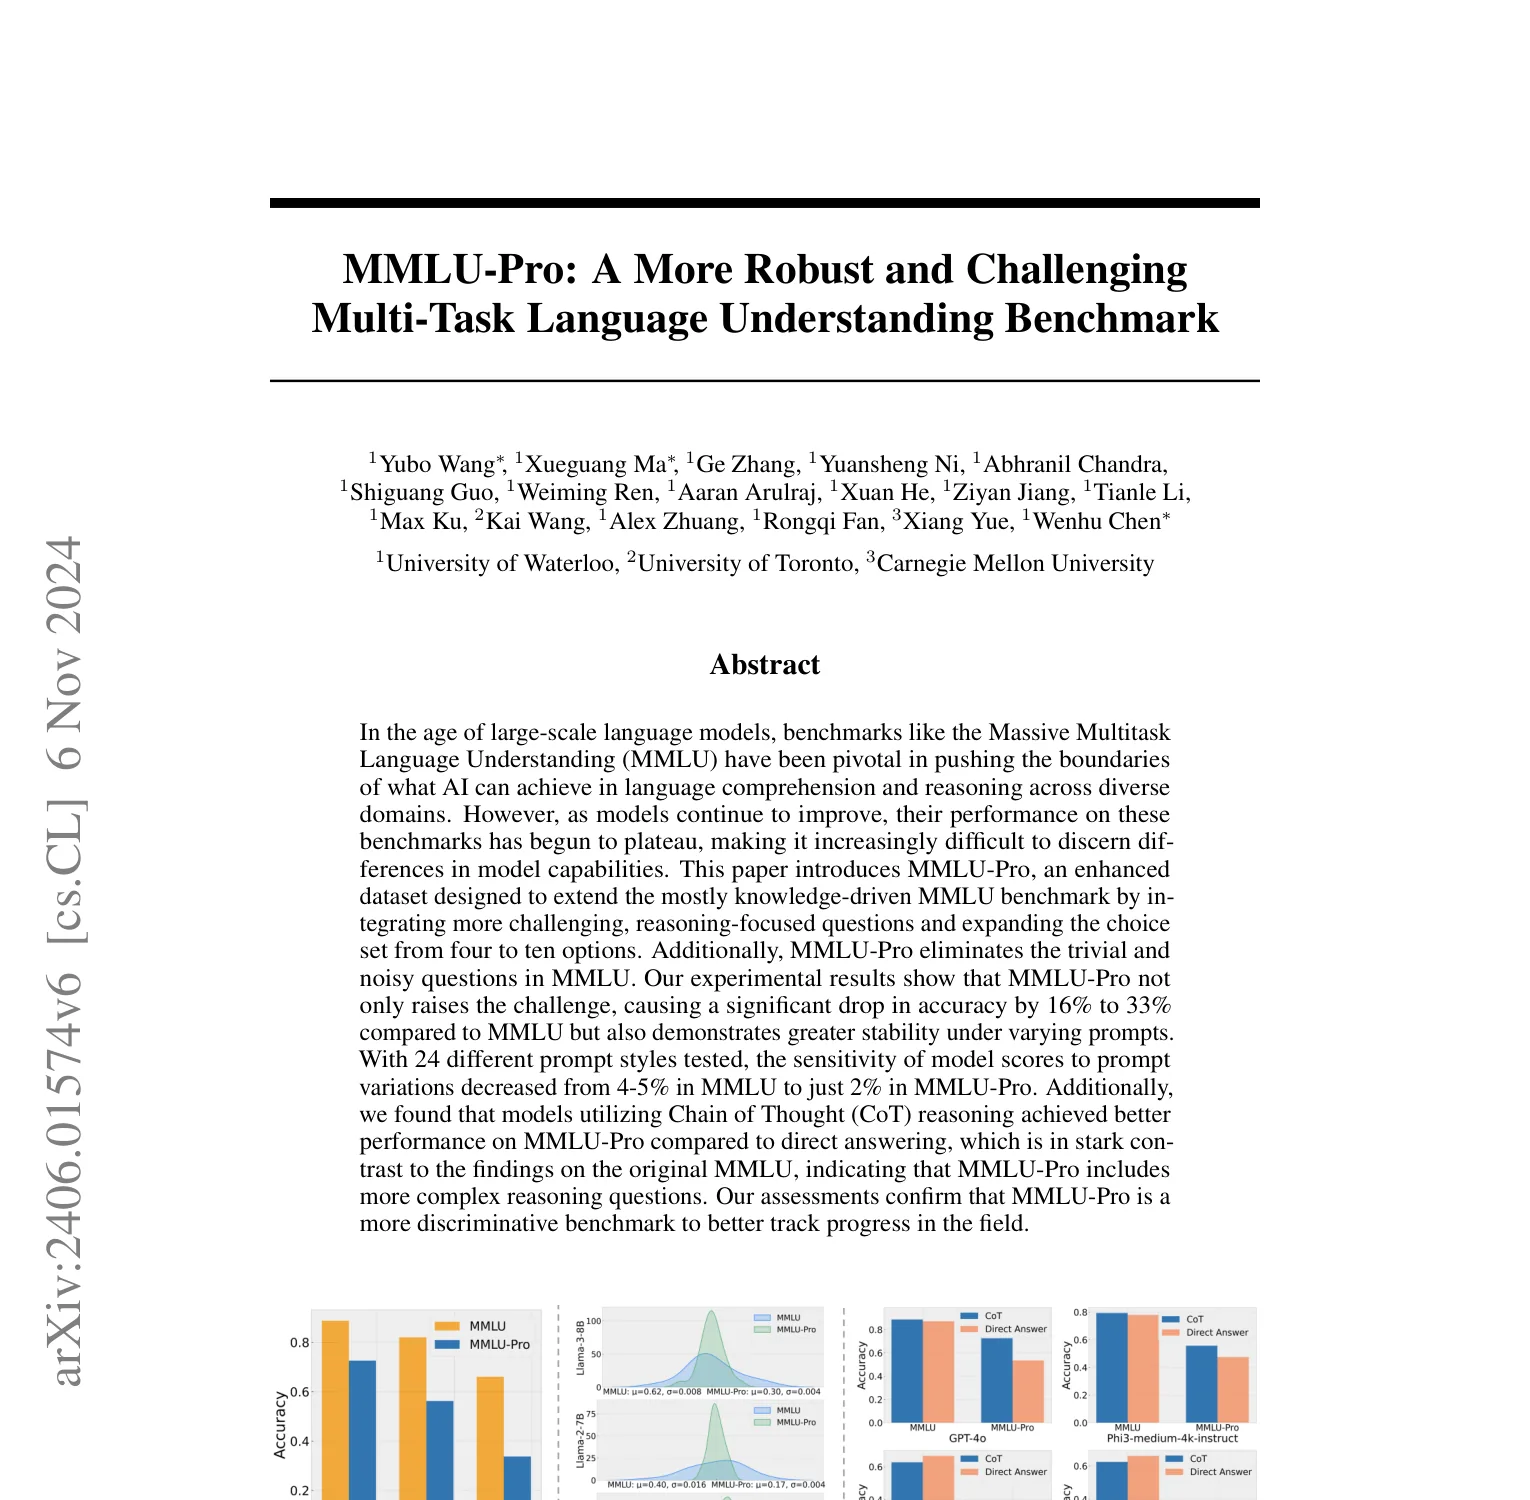
Across 24 prompt styles, MMLU-Pro scores varied less than MMLU scores, even as the revised exam made accuracy harder to achieve.
The prompt becomes part of the measurement
Wang and colleagues created MMLU-Pro to extend the mostly knowledge-driven MMLU with reasoning-focused questions, ten answer options, and expert review of noisy items. Their evaluation covers more than 50 models and compares 24 prompt styles.
The authors report accuracy 16–33% lower than on MMLU, while prompt sensitivity fell from 4–5% on MMLU to 2% on MMLU-Pro. Chain-of-thought improved performance on MMLU-Pro but hurt it on MMLU in their comparison. Those results distinguish the revised benchmark's reasoning demands and show how prompt selection affects reported scores.
MMLU-Pro is still a multiple-choice instrument built from selected questions and domains. Its stability result applies to the prompt styles tested; a single prompt's score does not represent that variation. In this paper, prompt family is part of the measurement record alongside accuracy.
Bibliography
- Yubo Wang; Xueguang Ma; Ge Zhang; Yuansheng Ni; Abhranil Chandra; Shiguang Guo; Weiming Ren; Aaran Arulraj; Xuan He; Ziyan Jiang; Tianle Li; Max Ku; Kai Wang; Alex Zhuang; Rongqi Fan; Xiang Yue; Wenhu Chen. (2024). MMLU-Pro: A More Robust and Challenging Multi-Task Language Understanding Benchmark. arXiv:2406.01574v6. https://arxiv.org/abs/2406.01574v6